Artificial Intelligence
How Deepgram optimized voice AI at scale with AWS Trainium
Deepgram worked with the AWS Forward Deployed Engineering team to port its Nova-3 speech-to-text model to AWS Trainium2 for offline batch inference. This post covers porting to the AWS Neuron stack, kernel-level tuning, a data-parallel Rust runtime, and the throughput and cost results on batch transcription.
Push-based KV transfer to improve TTFT and TPOT for disaggregated inference in vLLM
vLLM’s prefill-decode disaggregation splits LLM inference across engine instances but must transfer the KV cache between them. This post introduces a push-based NIXL connector that moves transfer coordination off the critical path, delivering up to 3x better TTFT and 30% better TPOT in benchmarks on Amazon EC2 P5en instances with AWS EFA.
Improve TTFT for multi-turn agentic workloads with bi-directional KV transfer in vLLM
Multi-turn agentic workloads reprocess growing conversation context each turn, driving up latency. See how bi-directional KV cache transfer lets prefill and decode nodes reuse previously computed context across turns, cutting time to first token by up to 1.6x for Qwen3-32B and 3.3x for GLM-5-FP8 on Amazon EC2 P5en instances with EFA.
Building trust in AI agents: A production-ready evaluation framework with Amazon Bedrock AgentCore
Autonomous AI agents fail softly: latency stays flat while answer quality quietly erodes. This post shares a nine-stage evaluation framework, built on Amazon Bedrock AgentCore, that catches silent quality regressions across the full agent lifecycle, from first commit to live production.
Introducing Reflection Beam: an open-weight model for agentic coding on AWS
Reflection AI’s Beam is an open-weight model for agentic coding and long-horizon tasks. This post shows how to deploy Beam on AWS: start with an Amazon SageMaker JumpStart real-time endpoint, or use Amazon SageMaker HyperPod Inference with JumpStart, SGLang, or vLLM for Kubernetes-native control over distributed GPU infrastructure.
Meta’s Muse Spark Open now available in Amazon SageMaker JumpStart
Muse Spark Open, Meta’s coding-optimized open-weight model, is now available in Amazon SageMaker JumpStart. Deploy it to a SageMaker AI endpoint in your own AWS account using SageMaker Studio or the SageMaker Python SDK, and run your first inference request.
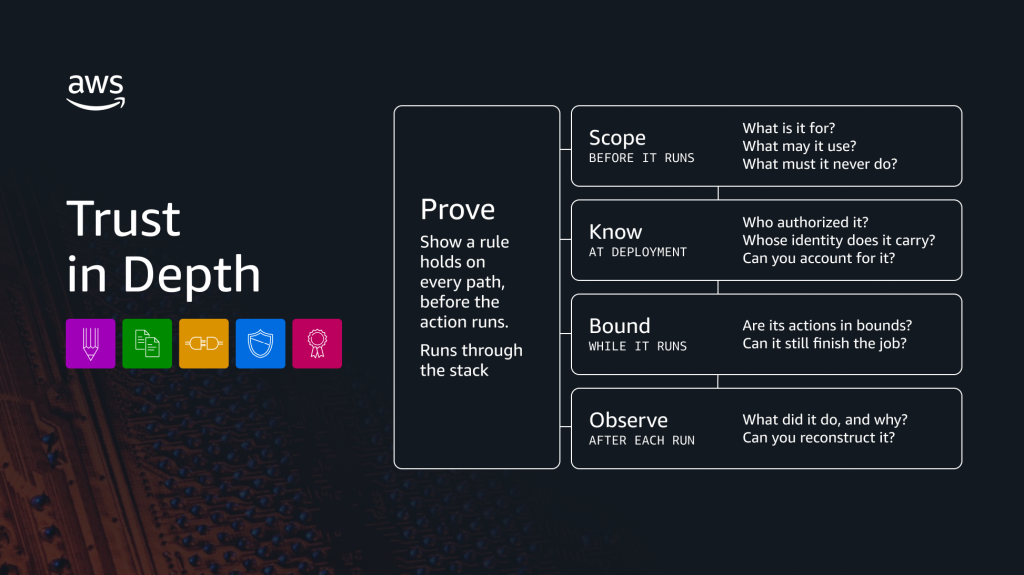
Trust in Depth: Giving agents more autonomy without losing control
Enterprise leaders want AI agents to take on more work but don’t fully trust them to act correctly every time. Trust in Depth is AWS’s layered approach-scope, know, bound, observe, and prove-that lets agents act on their own when their actions can be verified, reserving human judgment for the decisions that need it.
Build self-improving document processing using Amazon Bedrock AgentCore
Learn how to build an agentic intelligent document processing (IDP) system using Amazon Bedrock AgentCore that classifies, extracts, validates, and learns from business documents with minimal human intervention, automatically handling new document formats without manual template configuration.
Generate presentations with Amazon Bedrock AgentCore
This post walks you through building an AI agent system with Amazon Bedrock AgentCore that automates PowerPoint presentation creation from enterprise documents. A supervisor agent, Retrieval Augmented Generation, and Amazon Bedrock Guardrails generate grounded presentations in under 90 seconds.
How Tamnoon built AI-powered cloud security remediation with Amazon Bedrock
Learn how Tamnoon built Tami, an agentic cloud remediation orchestrator on Amazon Bedrock that autonomously investigates and safely remediates cloud security findings from CNAPP and cloud-native sources. The approach drove a 90%+ reduction in critical cloud exposure in 90 days with zero production issues.